HiMu: Hierarchical Multimodal Frame Selection for Long Video Question Answering
Picks 16 frames that beat 64 uniformly sampled ones on Video-MME, without any training.
Key result
With 16 frames chosen by HiMu, a training-free frame selector for long-video question answering, Qwen3-VL-8B scores 73.2% on Video-MME, above its 71.7% with 64 uniformly sampled frames.
Abstract
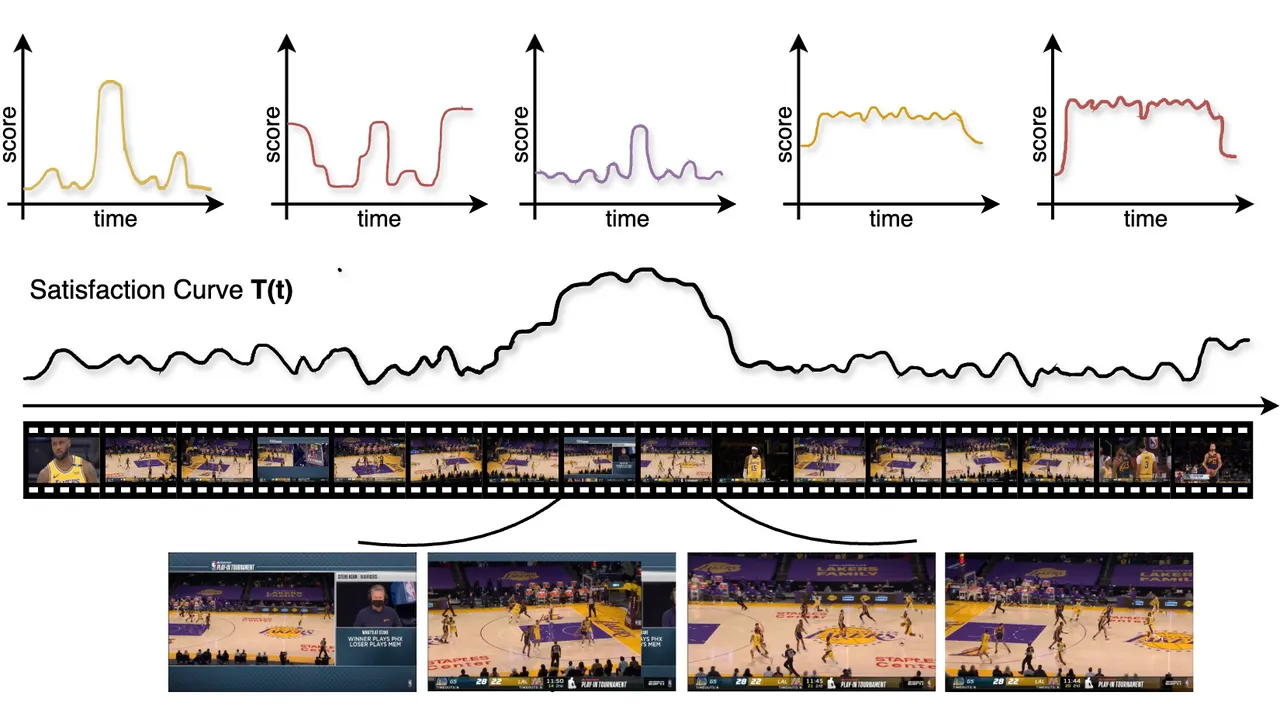
Long-form video question answering requires reasoning over extended temporal contexts, making frame selection a critical bottleneck for multi-modal large language models (MLLMs) bound by finite context windows. Within the controlled frame-budget regime that governs practical deployment, prior selectors score frames against a single global query embedding; as a result, compositional multimodal questions that involve temporal ordering or cross-modal cues such as “what happens on screen right after the narrator mentions the reaction?” are flattened into a representation that loses sub-event ordering and modality bindings. We introduce HiMu, a training-free framework for compositional multimodal frame selection. A single text-only LLM call decomposes the query into a hierarchical logic tree whose leaves are atomic predicates, each routed to a lightweight expert spanning vision (CLIP, open-vocabulary detection, OCR) and audio (speech recognition and non-speech sound matching). Expert signals are normalized, smoothed to align across modalities, and composed bottom-up through fuzzy-logic operators that enforce temporal sequencing and adjacency, yielding a continuous per-frame satisfaction curve. Under the standard 16-frame budget on Video-MME, LongVideoBench, and HERBench-Lite, HiMu achieves state-of-the-art accuracy among frame selection methods and improves over uniform sampling across seven diverse MLLMs as a drop-in module, matching the accuracy of uniform sampling at 4× its frame budget, without retraining and without multiple iterative MLLM calls during selection.
Abstract as published on arXiv.
Cite
@misc{benami2026himuhierarchicalmultimodalframe,
      title={HiMu: Hierarchical Multimodal Frame Selection for Long Video Question Answering},
      author={Dan Ben-Ami and Gabriele Serussi and Kobi Cohen and Chaim Baskin},
      year={2026},
      eprint={2603.18558},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2603.18558},
}
Topics
- frame selection
- long video question answering
- multimodal large language models
- training-free
- neuro-symbolic reasoning
- audio-visual
Related research
Long-video understanding: Benchmarks that show where Video-LLMs fail, and methods that let them look at less or train less.