VEDJE: Video-Efficient Discriminative Joint Encoder for Scalable Video-Text Retrieval
Matches a 7.6B-parameter multimodal LLM retriever on MSR-VTT with about 157M online parameters.
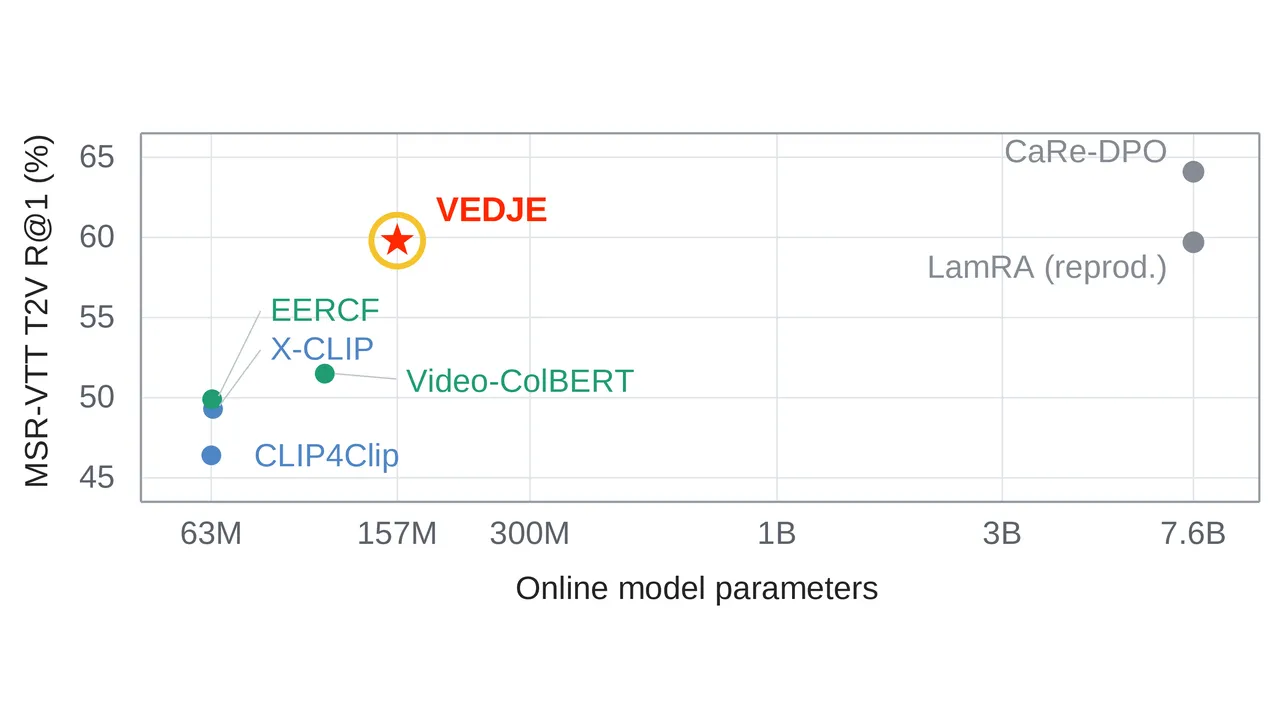
Key result
VEDJE matches a 7.6B-parameter multimodal LLM retriever on MSR-VTT text-to-video retrieval (59.8 against 59.7 R@1) with about 157M online parameters, roughly 48 times fewer, by encoding each video once into a compact cache read by a 33M-parameter reranker.
Abstract
Finding the right video often requires distinguishing similar scenes in which different events occur. Joint matching improves retrieval, but processing rich video representations for each query is costly. VEDJE compresses features within sampled frames while keeping their representations separate in a reusable cache. Feature-change prediction supplies an auxiliary training signal that improves retrieval from the compressed cache without adding work at query time. On MSR-VTT, MSVD, DiDeMo, and ActivityNet, VEDJE improves R@1 over matched first-stage retrievers in both retrieval directions. On MSR-VTT, it reaches 59.8 text-to-video R@1 with a fine-tuned VideoCLIP-XL first stage. In the VideoPrism configuration, shrinking the per-video cache fourfold to 12 KiB preserves text-to-video recall within 0.2 points. These results show that accurate video search can operate on compact evidence, encoded once and reused as new queries arrive.
Abstract as published on arXiv.
Cite
@misc{wagner2026vedjevideoefficientdiscriminativejoint,
      title={VEDJE: Video-Efficient Discriminative Joint Encoder for Scalable Video-Text Retrieval},
      author={Shahaf Wagner and Gabriele Serussi and Dan Ben Ami and Tomer Galanti and Chaim Baskin},
      year={2026},
      eprint={2610.11850},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2610.11850},
}
Topics
- video-text retrieval
- reranking
- cross-encoder
- video caching
- efficient retrieval
- MSR-VTT
Related research
Long-video understanding: Benchmarks that show where Video-LLMs fail, and methods that let them look at less or train less.
* Equal contribution.