Publications

2027

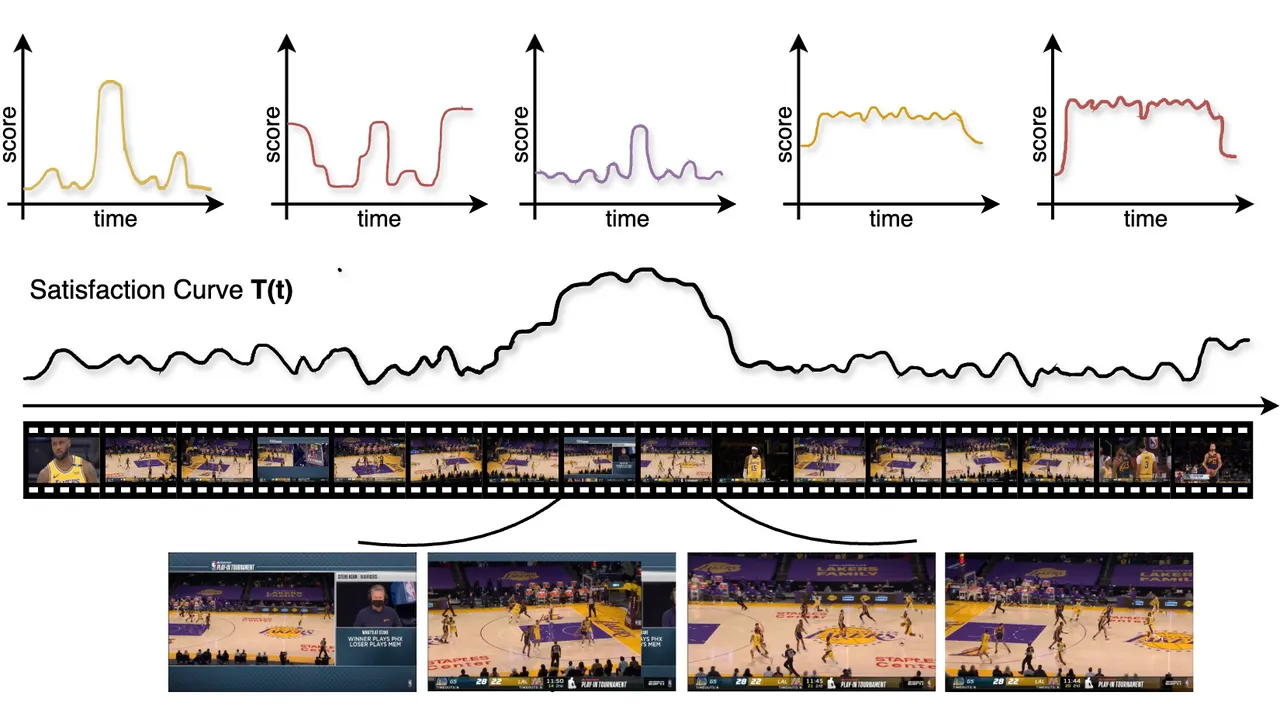
  • Score curves from several experts over a basketball broadcast, combined into one satisfaction curve that picks four frames.

    HiMu: Hierarchical Multimodal Frame Selection for Long Video Question Answering

    Dan Ben-Ami, Gabriele Serussi, Kobi Cohen, Chaim Baskin

    WACV 2027

    With 16 frames chosen by HiMu, a training-free frame selector for long-video question answering, Qwen3-VL-8B scores 73.2% on Video-MME, above its 71.7% with 64 uniformly sampled frames.

    BibTeX
    @misc{benami2026himuhierarchicalmultimodalframe,
          title={HiMu: Hierarchical Multimodal Frame Selection for Long Video Question Answering},
          author={Dan Ben-Ami and Gabriele Serussi and Kobi Cohen and Chaim Baskin},
          year={2026},
          eprint={2603.18558},
          archivePrefix={arXiv},
          primaryClass={cs.CV},
          url={https://arxiv.org/abs/2603.18558},
    }
2026

  • HERBench: A Benchmark for Multi-Evidence Integration in Video Question Answering

    Dan Ben-Ami*, Gabriele Serussi*, Kobi Cohen, Chaim Baskin

    CVPR 2026Co-first author11k+ dataset downloads

    HERBench forces video models to aggregate evidence: each of its 26,806 questions needs at least three separate cues from distinct parts of the video, and 13 state-of-the-art Video-LLMs reach only 31 to 42% (random is 20%).

    BibTeX
    @InProceedings{Ben_Ami_2026_CVPR,
        author    = {Ben Ami, Dan and Serussi, Gabriele and Cohen, Kobi and Baskin, Chaim},
        title     = {HERBench: A Benchmark for Multi-Evidence Integration in Video Question Answering},
        booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
        month     = {June},
        year      = {2026},
        pages     = {4505-4514}
    }
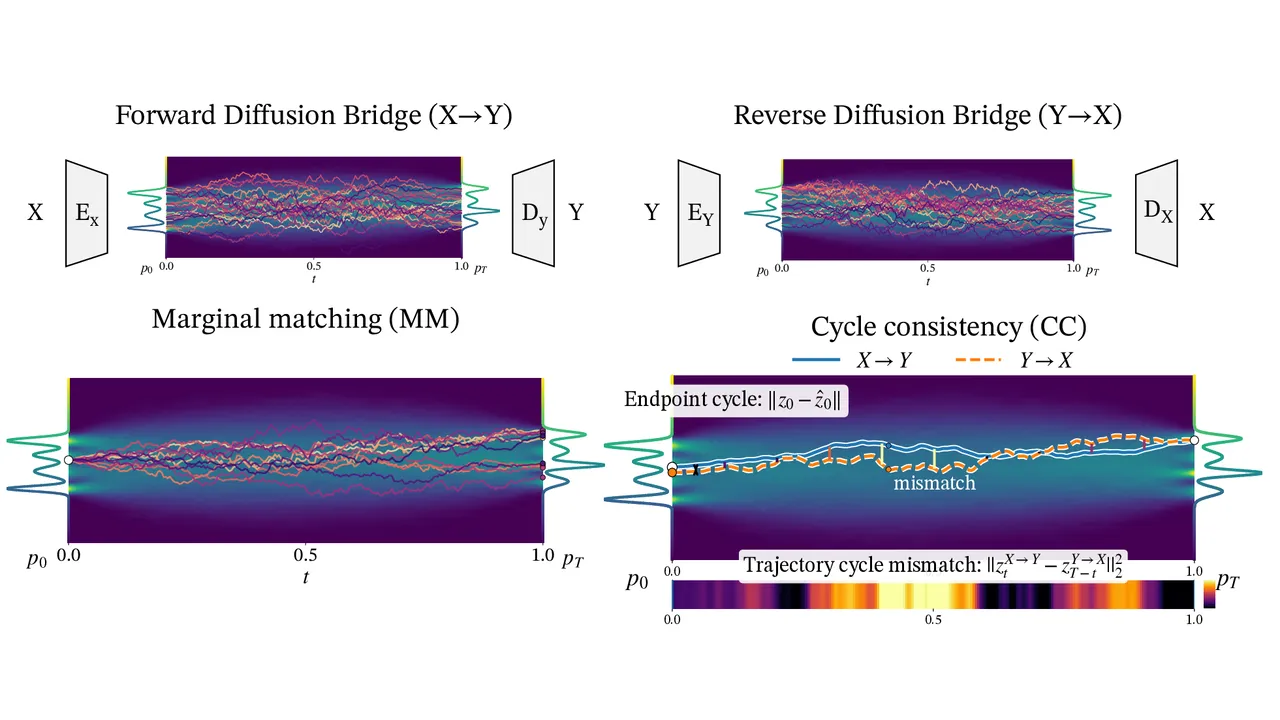
  • Forward and reverse diffusion bridges between two modalities, with the marginal matching and cycle consistency constraints drawn over their trajectories.

    Structured Diffusion Bridges: Inductive Bias for Denoising Diffusion Bridges

    Eitan Kosman, Gabriele Serussi, Chaim Baskin

    ICML 2026

    Structured Diffusion Bridges reach near fully paired quality in modality translation with half the paired data, 25.2 PSNR against 25.6 for a fully paired baseline on zero-shot super-resolution, and still learn with no pairs at all.

    BibTeX
    @inproceedings{kosman2026structured,
    title={Structured Diffusion Bridges: Inductive Bias for Denoising Diffusion Bridges},
    author={Eitan Kosman and Gabriele Serussi and Chaim Baskin},
    booktitle={Forty-third International Conference on Machine Learning},
    year={2026},
    url={https://openreview.net/forum?id=nWI6lV7BvA}
    }
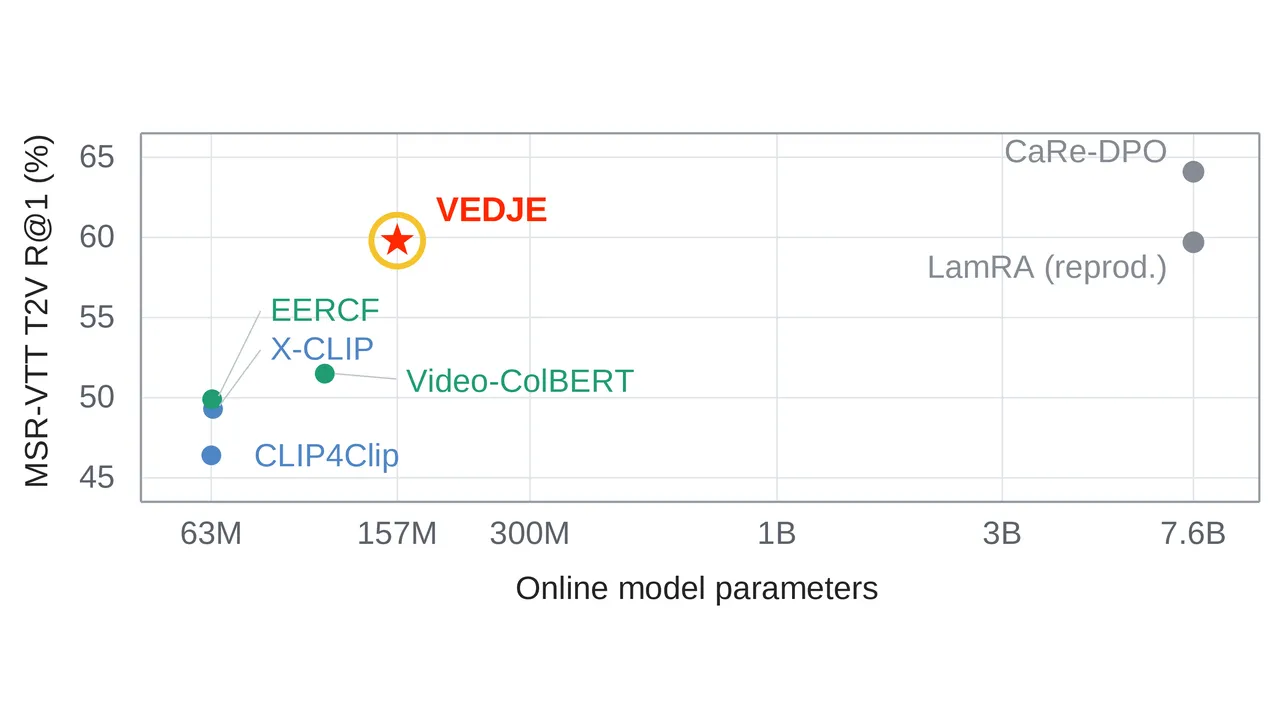
  • Plot of MSR-VTT text-to-video R@1 against online model parameters, with VEDJE marked at 59.8 and about 157M parameters among published systems from 63M to 7.6B.

    VEDJE: Video-Efficient Discriminative Joint Encoder for Scalable Video-Text Retrieval

    Shahaf Wagner*, Gabriele Serussi*, Dan Ben Ami, Tomer Galanti, Chaim Baskin

    ICML 2026 Workshop (AdaptFM)Co-first author

    VEDJE matches a 7.6B-parameter multimodal LLM retriever on MSR-VTT text-to-video retrieval (59.8 against 59.7 R@1) with about 157M online parameters, roughly 48 times fewer, by encoding each video once into a compact cache read by a 33M-parameter reranker.

    BibTeX
    @misc{wagner2026vedjevideoefficientdiscriminativejoint,
          title={VEDJE: Video-Efficient Discriminative Joint Encoder for Scalable Video-Text Retrieval},
          author={Shahaf Wagner and Gabriele Serussi and Dan Ben Ami and Tomer Galanti and Chaim Baskin},
          year={2026},
          eprint={2610.11850},
          archivePrefix={arXiv},
          primaryClass={cs.CV},
          url={https://arxiv.org/abs/2610.11850},
    }
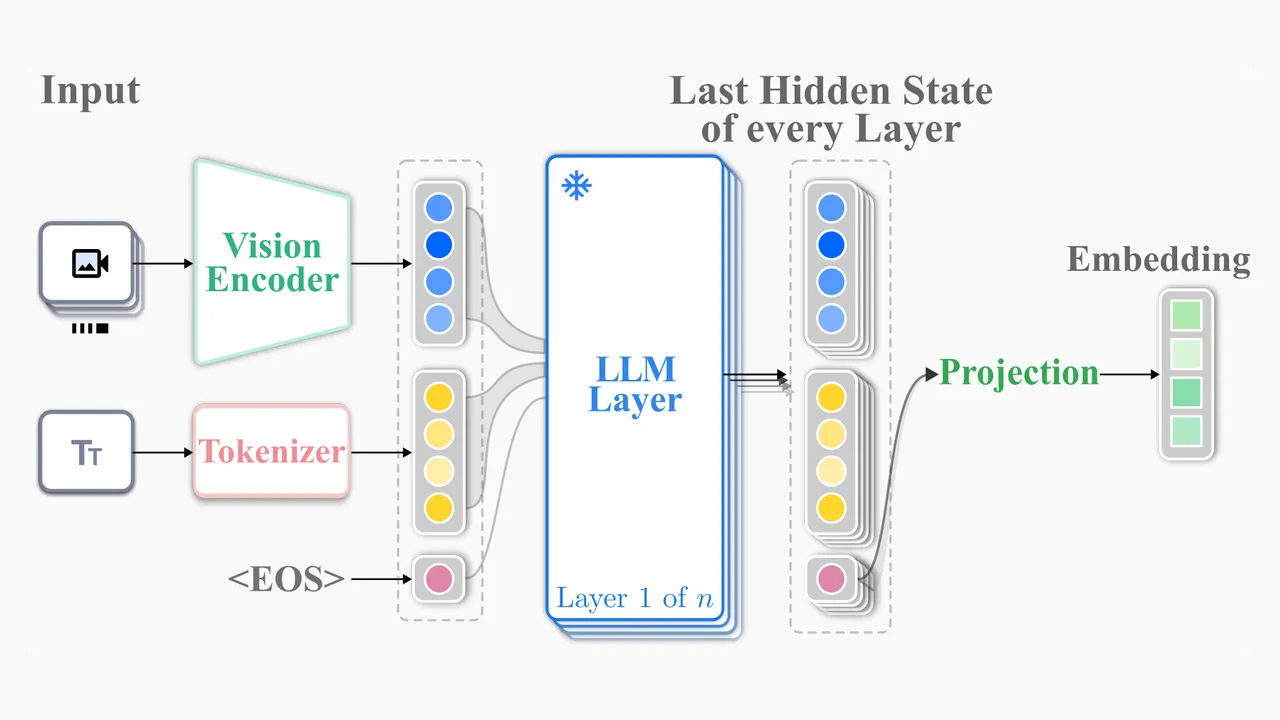
  • PREGEN pipeline: video and text tokens pass through a frozen LLM, and the final-token hidden state of every layer is pooled by a small encoder into one embedding.

    PREGEN: Uncovering Latent Thoughts in Composed Video Retrieval

    Gabriele Serussi*, David Vainshtein*, Jonathan Kouchly*, Dotan Di Castro, Chaim Baskin

    arXiv 2026Co-first author

    PREGEN reaches 99.73 Recall@1 on WebVid-CoVR, 27.23 points above the previous best, by reading a frozen VLM's hidden states with a lightweight encoder for composed video retrieval.

    BibTeX
    @misc{serussi2026pregenuncoveringlatentthoughts,
          title={PREGEN: Uncovering Latent Thoughts in Composed Video Retrieval},
          author={Gabriele Serussi and David Vainshtein and Jonathan Kouchly and Dotan Di Castro and Chaim Baskin},
          year={2026},
          eprint={2601.13797},
          archivePrefix={arXiv},
          primaryClass={cs.CV},
          url={https://arxiv.org/abs/2601.13797},
    }

2024

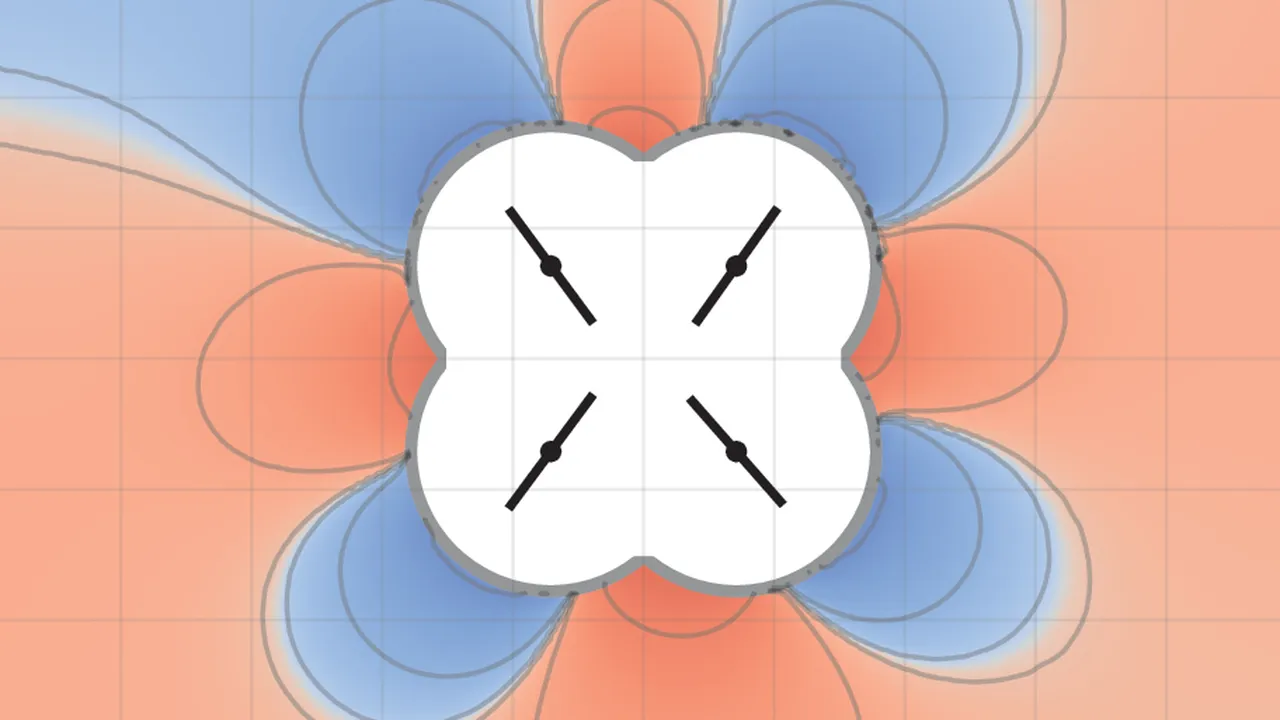
  • Simulated sound pressure around a four-rotor drone in a square room, with positive pressure in red and negative in blue.

    Active propulsion noise shaping for multi-rotor aircraft localization

    Gabriele Serussi*, Tamir Shor*, Tom Hirshberg, Chaim Baskin, Alex M. Bronstein

    IROS 2024Oral pitchCo-first author

    Also presented at ICML 2024 Workshop (AI4Science).

    Learning a drone's rotor phases together with a neural localizer lets it localize itself from its own propulsion noise, more than 2.7 times better in simulation than the best handcrafted modulation.

    BibTeX
    @inproceedings{Serussi_2024,
      title={Active propulsion noise shaping for multi-rotor aircraft localization},
      url={http://dx.doi.org/10.1109/IROS58592.2024.10802115},
      DOI={10.1109/iros58592.2024.10802115},
      booktitle={2024 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS)},
      publisher={IEEE},
      author={Serussi, Gabriele and Shor, Tamir and Hirshberg, Tom and Baskin, Chaim and Bronstein, Alex M.},
      year={2024},
      month=oct,
      pages={472--479}
    }

* Equal contribution.