PREGEN: Uncovering Latent Thoughts in Composed Video Retrieval
Reads a frozen VLM's hidden states to reach 99.73 Recall@1 on WebVid-CoVR, 27.23 points above the previous best.
Key result
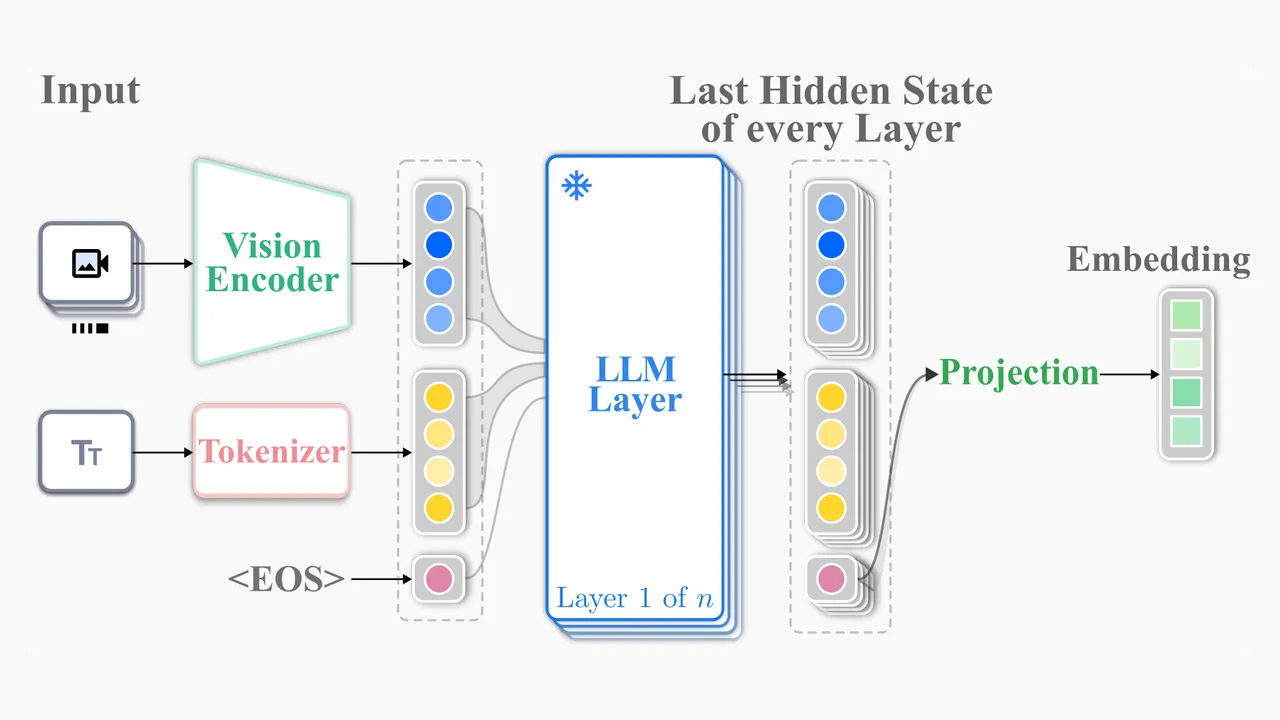
PREGEN reaches 99.73 Recall@1 on WebVid-CoVR, 27.23 points above the previous best, by reading a frozen VLM's hidden states with a lightweight encoder for composed video retrieval.
Abstract
Composed Video Retrieval (CoVR) aims to retrieve a video based on a query video and a modifying text. Current CoVR methods fail to fully exploit modern Vision-Language Models (VLMs), either using outdated architectures or requiring computationally expensive fine-tuning and slow caption generation. We introduce PREGEN (PRE GENeration extraction), an efficient and powerful CoVR framework that overcomes these limitations. Our approach uniquely pairs a frozen, pre-trained VLM with a lightweight encoding model, eliminating the need for any VLM fine-tuning. We feed the query video and modifying text into the VLM and extract the hidden state of the final token from each layer. A simple encoder is then trained on these pooled representations, creating a semantically rich and compact embedding for retrieval. PREGEN significantly advances the state of the art, surpassing all prior methods on standard CoVR benchmarks with substantial gains in Recall@1 of +27.23 and +69.59. Our method demonstrates robustness across different VLM backbones and exhibits strong zero-shot generalization to more complex textual modifications, highlighting its effectiveness and semantic capabilities.
Abstract as published on arXiv.
Cite
@misc{serussi2026pregenuncoveringlatentthoughts,
      title={PREGEN: Uncovering Latent Thoughts in Composed Video Retrieval},
      author={Gabriele Serussi and David Vainshtein and Jonathan Kouchly and Dotan Di Castro and Chaim Baskin},
      year={2026},
      eprint={2601.13797},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2601.13797},
}
Topics
- composed video retrieval
- vision-language models
- frozen VLM
- hidden states
- WebVid-CoVR
Related research
Long-video understanding: Benchmarks that show where Video-LLMs fail, and methods that let them look at less or train less.
* Equal contribution.